LUISUAN Technology appeared at Asia Venture Capital Night, revealing how to increase GPU utilization to 94%?
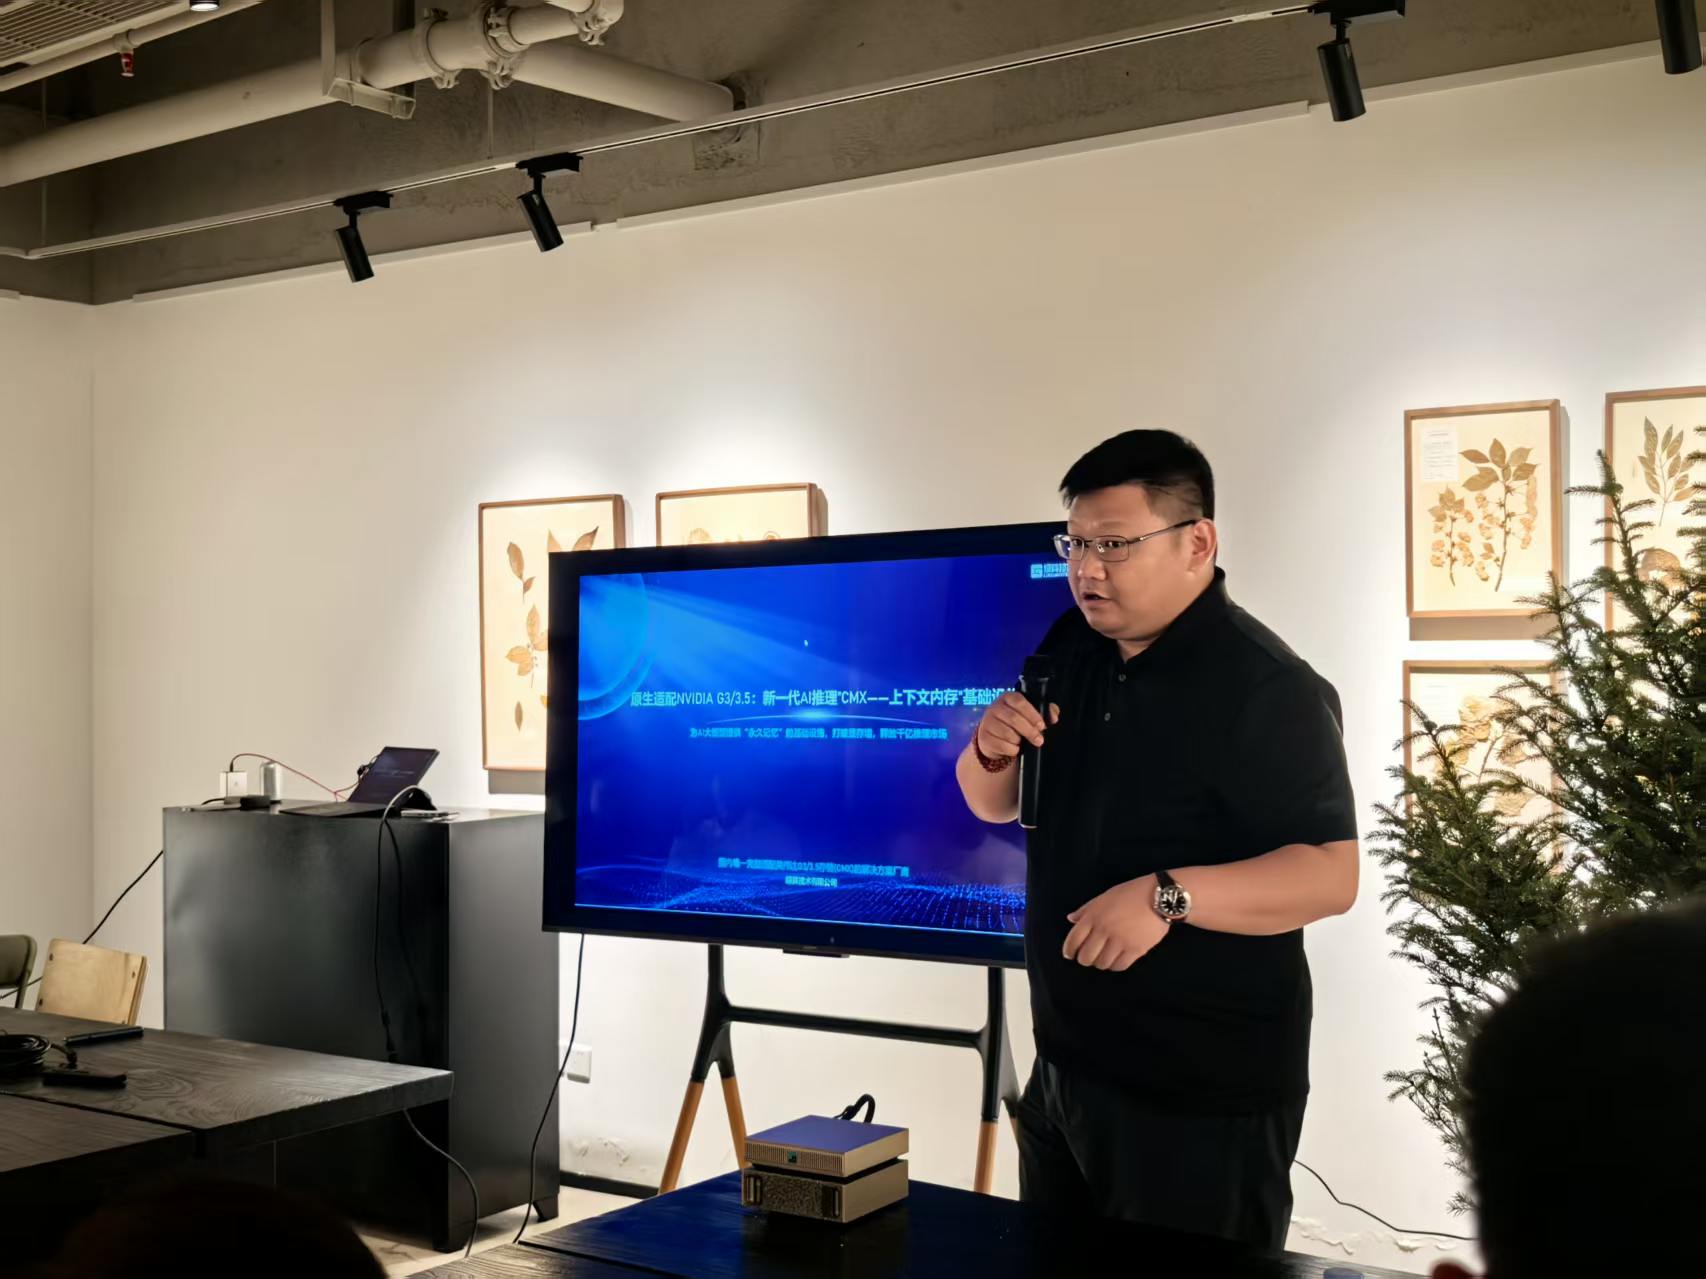
The high-end venture capital event "AI NATIVE NIGHT·Asia Venture Capital Night" jointly sponsored by elawtime, One Step and Xinjin Venture Capital concluded successfully in Qiantan, Shanghai. At this private gathering that brought together top investors, AI unicorn founders and industry leaders, Huang Fei, general manager of the LUISUAN Technology Marketing Management Center, delivered a speech titled "Native Adaptation to NVIDIA G3/3.5: New Generation AI Inference "CMX - Contextual Memory" Infrastructure"'s keynote speech analyzed the core pain points of commercialization of large AI models from a cutting-edge perspective, and demonstrated the hard-core strength of LUISUAN Technology as "the only domestic manufacturer that fully adapts to NVIDIA G3/3.5 storage (CMX)", becoming the focus of the audience.
Facing the 100-billion-level bottleneck: Breaking the “graphics memory wall” dilemma of AI reasoning
At the beginning of the speech, Huang Fei directly hit the core pain point in the current field of AI reasoning: "As large models evolve to long contexts (such as millions of Tokens), the KV Cache (key value cache) grows exponentially, while the expensive GPU memory (HBM) is limited by physical capacity and cost, and its linear growth is weak. This has led to a serious 'memory wall' phenomenon, leaving GPU computing power idle, making it difficult to implement high-value ultra-long texts and high-concurrency application scenarios."
He pointed out that Nvidia defined a new level of G3/3.5 CMX (Context Memory Extension) storage precisely to solve this problem. According to a Citi report, this solution will drive global NAND demand, accounting for as high as 9.3% by 2027. This is not only a technical optimization, but also a paradigm revolution in AI infrastructure.
Dismantling of hard-core technology: full-stack self-research to build “permanent memory”
As the only solution manufacturer in China that adapts to the NVIDIA G3/3.5 CMX standard, LUISUAN Technology has demonstrated its complete path to building a "permanent memory" infrastructure for large AI models. Mr. Huang Fei introduced in detail LUISUAN’s “fully self-developed hardware offloading architecture”:
1. Intelligent scheduling layer (software-defined "brain")
Function: Global KV Cache resource pool management, predictive data scheduling.
Ecological adaptation: Already adapted to NVIDIA Dynamo, Huawei UCM, and Tencent FlexKV.
Core value: Active scheduling, rather than passive caching, to achieve seamless and intelligent flow of data between GPU memory and G3 storage.
2. Hardware acceleration layer (self-developed "data nerve")
Core technology: GP7000 adopts DPU+ASIC+FPGA heterogeneous architecture, solidifying the full link of RDMA and NVMe-oF protocol stack in the chip to realize full hardware protocol stack offloading.
Core value: Completely eliminate CPU bottlenecks and achieve end-to-end
3. High-speed storage layer (optimizing "storage muscle")
Function: Flash management and cluster architecture deeply optimized for KV Cache access model.
Core value: Provide stable and extremely high IOPS and bandwidth to meet the data "throughput" requirements of the GPU.
Evidence of computing power doubling: GPU utilization approaching 95%
Ecological panorama: the unified base of three major technical routes
Regarding the current mainstream AI reasoning architecture, Mr. Huang Fei demonstrated the broad compatibility of LUISUAN Technology:
NVIDIA Dynamo Ecosystem: As the first mass-produced G3.5 CMX platform in China, GP7000 builds a four-layer closed loop of "scheduling → decision-making → transmission → hardware execution". GP7000 serves as the L1 hardware layer carrier.Natively supports DOCA/BF3/Spectrum-X/GDS full-stack ecosystem.
Mooncake (Dark Side of the Moon): GP7000 serves as the fourth level of persistent storage (G3.5 layer), extending the cache capacity to the PB level. It plays three core roles in Mooncake: buffer overflow pool (LRU elimination writes), long context persistence (millions of Tokens are stored in chunks), and cross-cluster shared pool (zero-cost migration).
LMCache (open source community): One line of code configuration, zero intrusion into the vLLM model. Based on GP Spark+LMCache+SupremeRAID
Measured data: The first token delay dropped from 187s to 8s (24 times improvement), the query throughput increased 11 times, and the KV Cache external hit rate reached 66.2%. .
Looking to the future: Continue to lead the AI storage track
Talking about the future, Huang Fei revealed that LUISUAN Technology is accelerating the development of the GP-8000 flagship platform adapted to NVIDIA BlueField-4 DPU, as well as the self-developed "Qingyi" storage ASIC chip, aiming to further reduce costs, improve performance, and continue to consolidate its leadership in the field of AI inference contextual memory.
At this Asia Venture Capital Night, LUISUAN Technology not only demonstrated its profound technical foundation and business potential to the capital market, but also conveyed the confidence of Chinese companies in the underlying innovation of AI infrastructure. Relying on the unique card position of "the first in China" and the technical barriers of full-stack self-research, LUISUAN Technology is becoming the core force to unlock the hundreds of billions of AI reasoning market.
In the future, LUISUAN Technology will continue to work with partners to inject strong impetus into the vigorous development of the global AI industry.