LUISUAN TECH
Let data flow efficiently
Comprehensive acceleration for computing
LUISUAN Technology independently develops GP series all-flash storage, with a single system up to 70 million IOPS and 2400Gbps aggregate bandwidth, building a new generation of data infrastructure for supercomputing centers, intelligent computing centers and industry customers.
LUISUAN TECH
CPUless architecture
Ultimate performance breakthrough
GP6000 all-flash storage uses a CPU-less, memory-less vector in-storage platform with 40 million IOPS, 1200Gbps aggregate bandwidth, and 4μs extreme latency to fully accelerate AI training and inference.
LUISUAN TECH
Domestic high performance
All-flash storage platform
GP5000 supports storage and computing separation architecture, 16 million IOPS, 600Gbps bandwidth, and 4μs ultra-low latency, providing a stable base for databases, virtualization, and private clouds.
LUISUAN TECH
GP Spark Series
AI Storage Companion · Plug and play
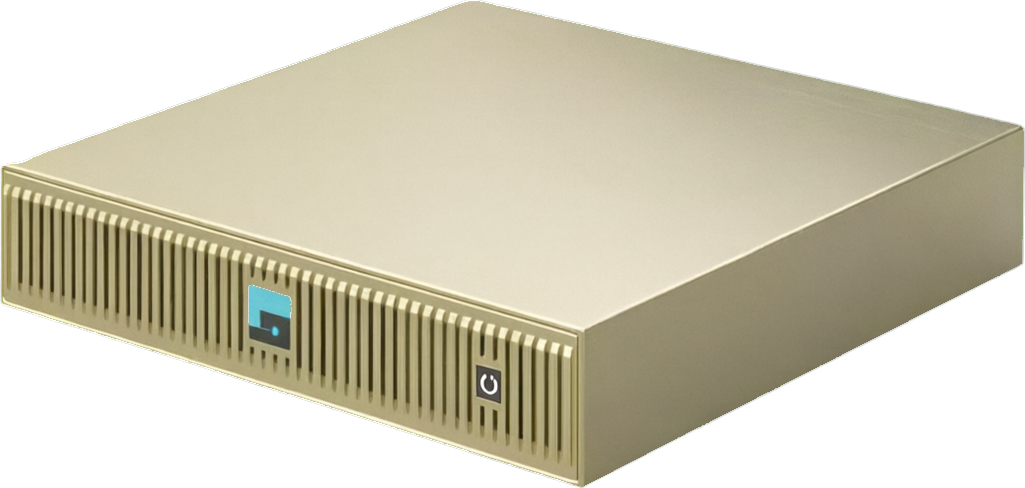
Data center-grade NVMe-oF storage node designed specifically for NVIDIA DGX Spark, hardware offload engine enables end-to-end data acceleration, plug-and-play, desktop-grade form factor.
Calculation by saving · Hard core technology base
From storage and computing separation architecture to chip-level acceleration, build a data infrastructure for the AI era.
Separation of deposits and calculations · Use deposits to force calculations
Diskless architecture and full-stack RDMA technology reduce remote access latency to the local level, with a single system up to 70 million IOPS.
Self-developed chip-level acceleration
The RoCE/NVMe-OF protocol offloads the chip and the PUF security chip to realize hardware-level data flow and security protection.
Open ecological mutual certification
Completed 200+ domestic and foreign product compatibility and mutual certification, fully compatible with NVIDIA and domestic computing power ecology.
Break the memory wall,A new level of AI native storage
NVIDIA proposed the G3.5 contextual memory (CMX) storage layer at GTC 2026. LUISUAN GP7000 is the first mass-produced G3.5 CMX platform in China. It offloads KV Cache from expensive HBM to Ethernet flash cluster (JBOF/EBOF), allowing the GPU to focus on token generation and building a new paradigm of AI intelligent storage for large models.
Natively compatible DOCA offloading framework, Dynamo scheduling and NIXL transport library, and support Mooncake, LMCache,Moon Storage Waiting for KV Cache uninstallation plan
KV Cache full hardware offload
- DPU+ASIC+FPGA multiple heterogeneous, full hardware offload KV Cache
- GPU utilization increased to over 94%
- Context recalculation ratio reduced from 80–90% to less than 10%
G3.5 contextual memory layer
- Benchmarking NVIDIA G3.5 storage architecture (CMX)
- <20μs microsecond latency, PB-level capacity
- Natively compatible with Dynamo scheduling and NIXL transport library
JBOF / EBOF Flash Cluster
- 24 PCIe 5.0 NVMe U.2 bays
- Single machine 70 million IOPS, 300GB/s bandwidth
- DPU+RDMA direct connection, bypassing CPU/PCIe bottlenecks
Hot, warm and cold stratification · Storage is memory
- KV Cache hot, warm and cold tiered intelligent management
- Resource utilization increased from 30% to over 70%
- TCO reduced by 30–50%, layout CXL memory pooling
Star product matrix
All-flash storage, computing acceleration and low-altitude detection cover multiple scenarios.
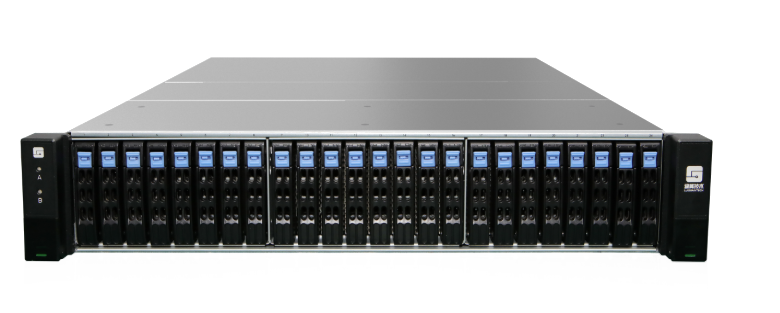
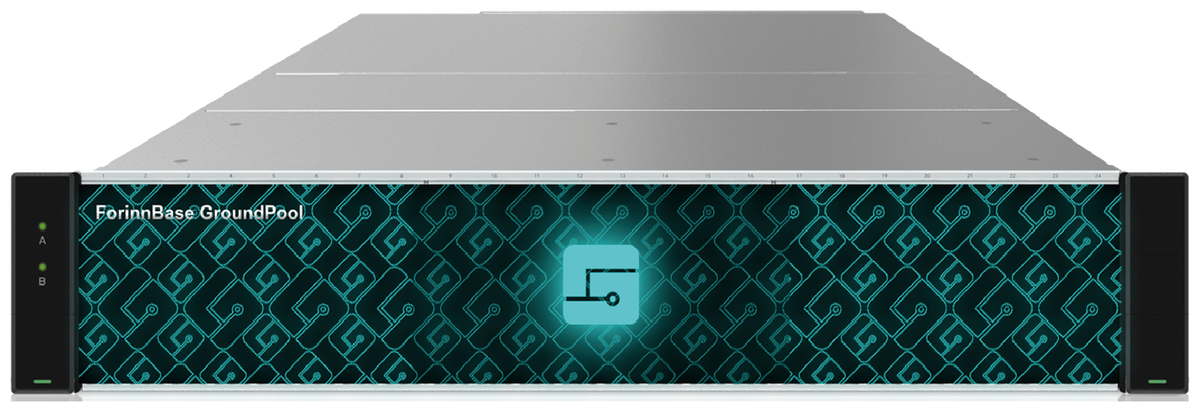
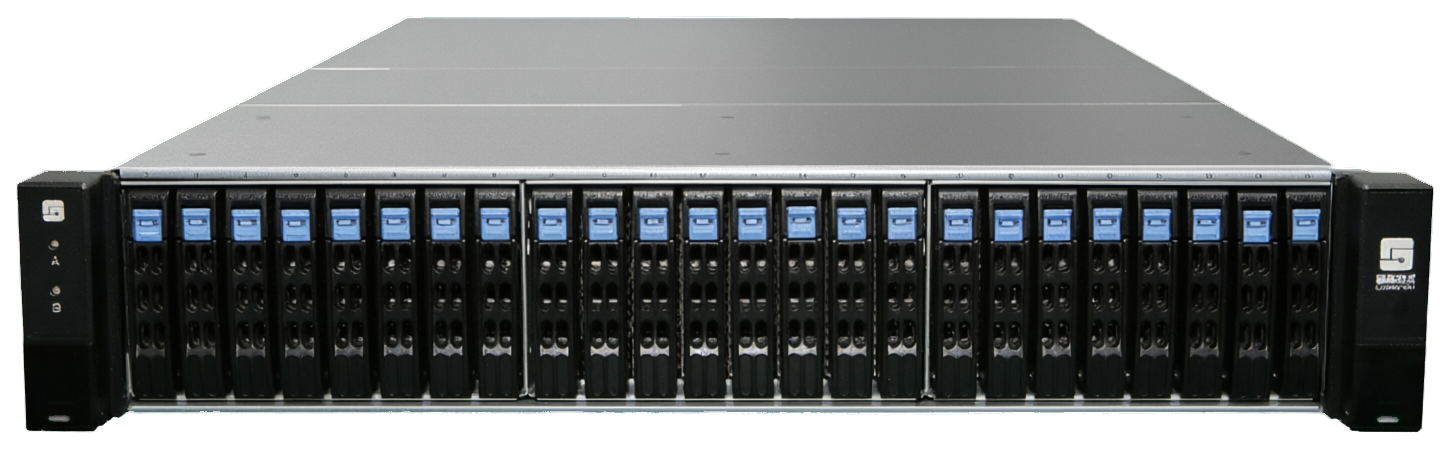
GP5000 series all-flash storage
A domestic high-performance all-flash storage platform with a compute-storage separation architecture, combining high throughput and ultra-low latency to reliably support core workloads in large-scale data centers.
GP5000-2401·GP5000-2402
Learn More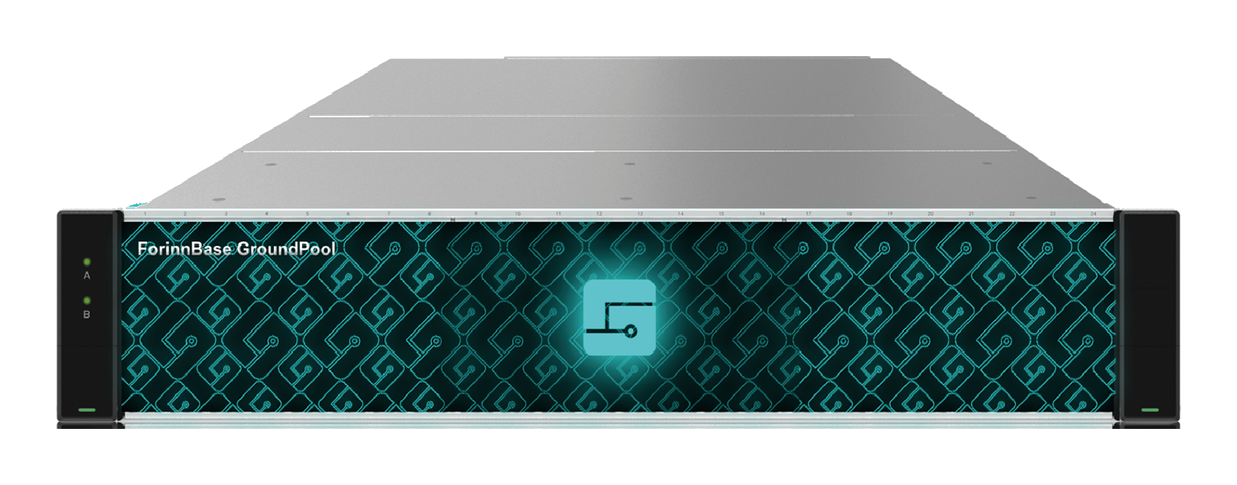
GP6000 series all-flash storage
A new-architecture all-flash storage platform with no CPU and no memory; up to 40 million IOPS, 192GB/s high throughput, and 4μs latency (to the SSD controller).
Learn More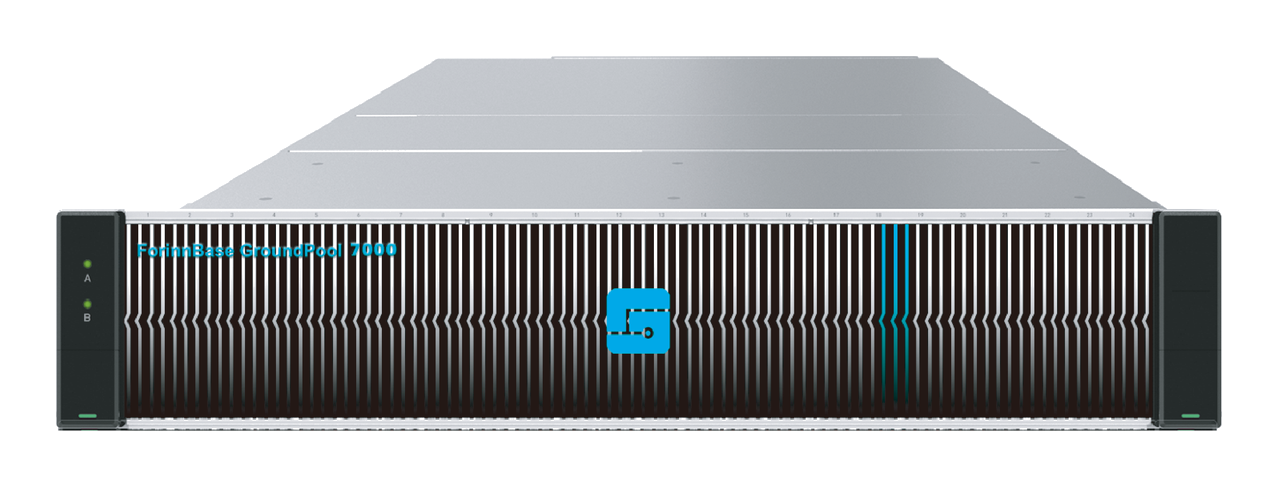
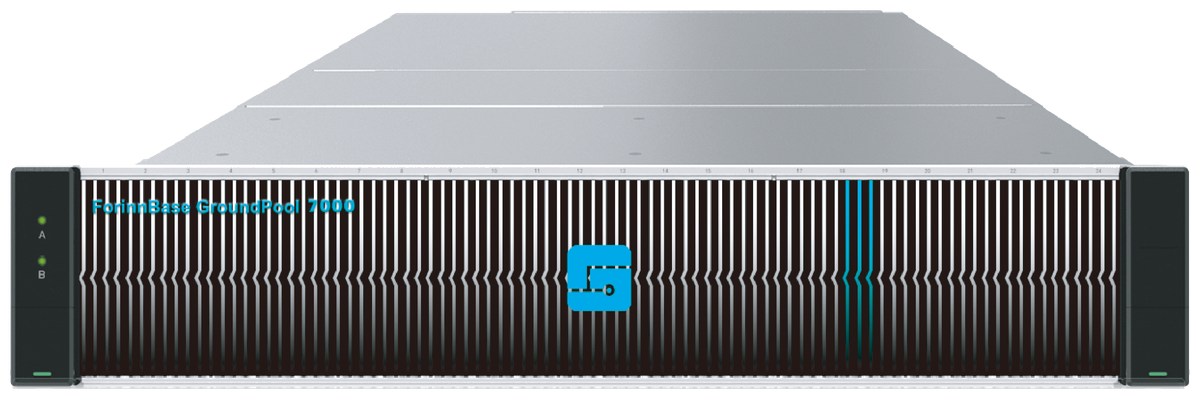
GP7000 high-performance all-flash storage platform
Specifically built for the AI era, benchmarked against NVIDIA G3 storage architecture, with 70 million IOPS per machine and <20μs latency.
Learn More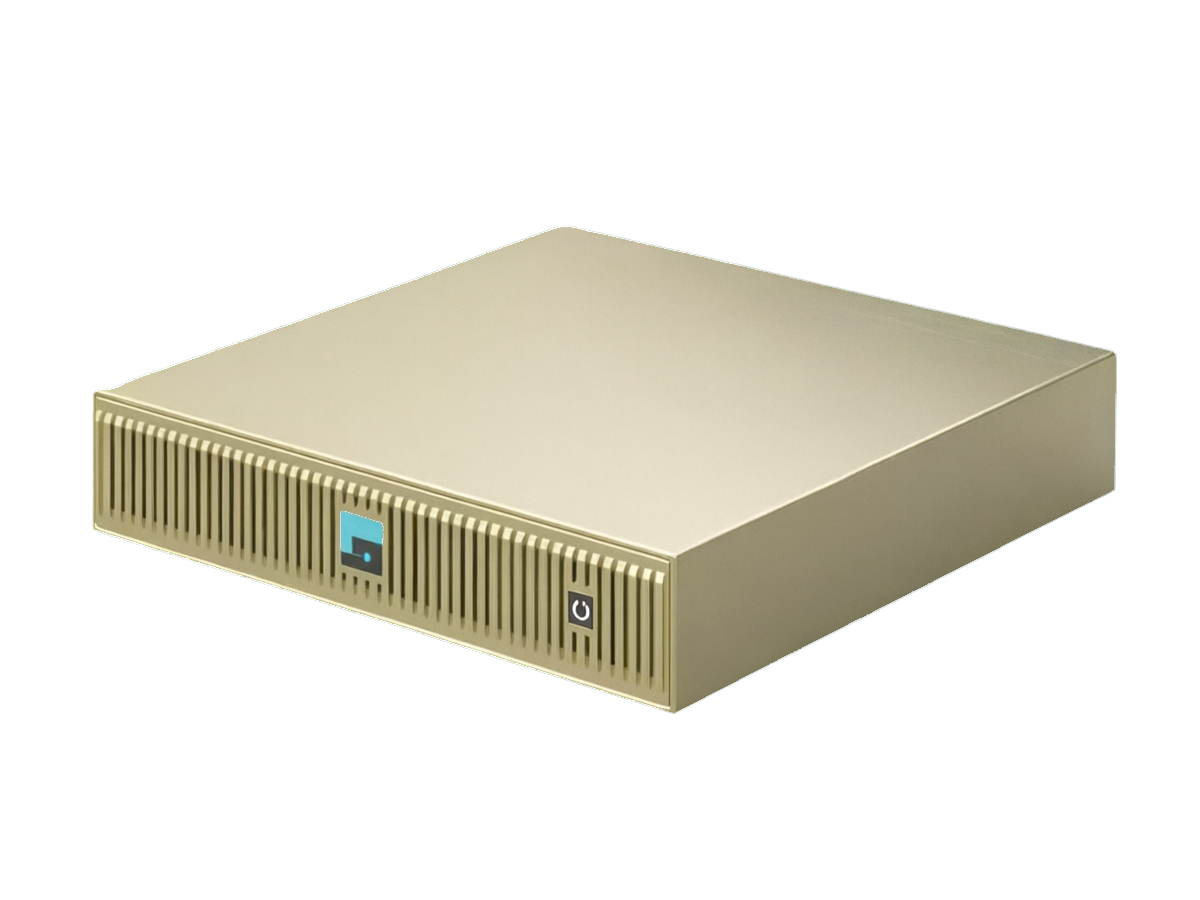
GP Spark AI Storage Companion
Data center-grade NVMe-oF storage node designed specifically for NVIDIA DGX Spark, hardware offload engine enables end-to-end data acceleration, plug-and-play, desktop-grade form factor.
GP Spark
Learn More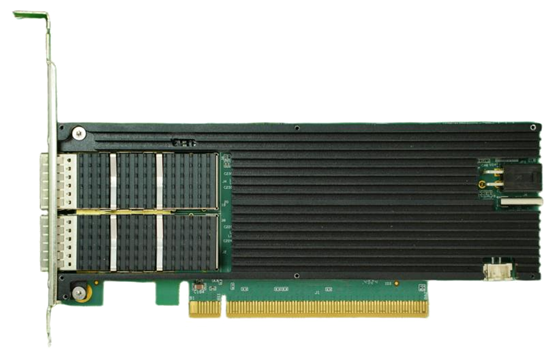
LightBoat-2300 LightBoat series FPGA accelerator card
A high-performance FPGA accelerator card based on AMD UltraScale+™ architecture and Virtex UltraScale+ XCVU23P chip, specially designed for scenarios such as intelligent networks, data center acceleration, AI inference, hardware security, and industrial edge computing.
Learn More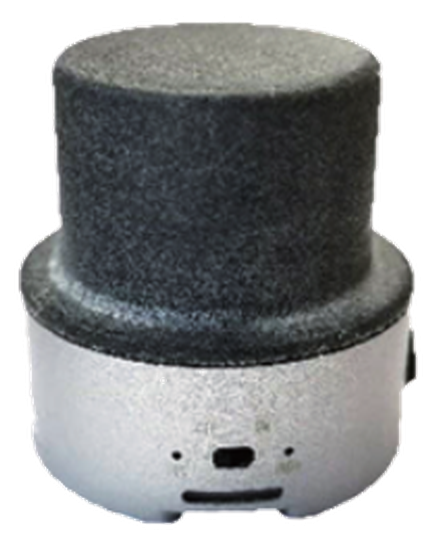
Deep combination UAV trajectory measurement system
An advanced measurement system specially designed for UAV flight inspection under various complex working conditions. It has a built-in deep combination algorithm and dual-antenna direction finding, data and status real-time backhaul functions. It is suitable for various types of UAV flight performance evaluation and mission load tactical indicator testing.
UAV-22-MUS (INS)·UAV-22-MUS (RTK)
Learn Morenewsdynamic
Get the latest company news and technological progress at your fingertips.
- 2026-09-18 LUISUAN Technology appeared at the "Technology and Finance" investment and financing ecological event, and gave a keynote speech on the new generation of AI inference infrastructure
- 2026-09-12 LUISUAN Technology debuted at the 2026 Service Trade Fair, and the Peregrine series GP SPARK was selected as the annual key overseas recommendation
- 2026-09-11 LUISUAN Technology's "Defining a New Level of AI Inference Storage: G3.5 Level KV Cache Solution" was selected as an outstanding achievement in AI intelligent computing innovation at the 2026 Smart Expo
- 2026-09-08 LUISUAN Technology GP7000 obtained the authoritative testing certification from China Academy of Information and Communications Technology Taier Laboratory
- 2026-09-05 Closing | The 2026 Open Data Center Conference and the First Computing Expo came to a successful conclusion: three major events in LUISUAN Technology made "storage power equals computing power" an industry consensus
- 2026-09-05 Solidigm and LUISUAN Technology jointly released the technical white paper "Storage Expansion Solution for SOHO AI Inference"
Are you ready to build the next generation of data infrastructure?
Welcome to contact us to get exclusive storage and computing solutions.
Inquire Now